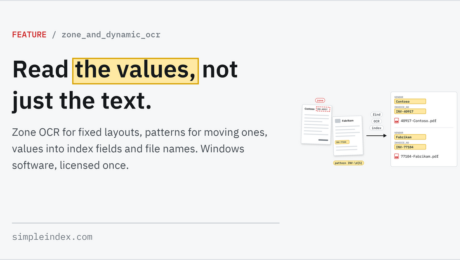
Zone OCR, also called zonal OCR, reads index values from a box drawn in the same place on every page. SimpleIndex pairs it with dynamic OCR, which finds a value anywhere on the page, so documents that shift in the scanner still read correctly. The posts below show zone OCR in real jobs.
Zone and dynamic OCR in SimpleIndex →
SimpleIndex 11.4 Release Notes
Friday, 05 September 2025
SimpleIndex 11.4 new version, adds major new features like an easy option to customize what emails need to be processed from email boxes by setting dates and subfolders and automatically updating them each time these emails are processed. Additionally, ChatGPT integration was added. This allows you to extract index values and text from any document
- Published in Release Notes
Automatic Image Splitting
Tuesday, 10 October 2023
Speed up scanning of multi-page layouts and spreads with SimpleIndex’s built-in tools Magazines, pamphlets, booklets and similar documents can be a scanning headache, particularly when you want to capture each page, or even each block of text, as its own separate file. Splitting the pages and cropping each one to its final format adds hours
Language Pack for Standard/Tesseract OCR
Monday, 01 November 2021
Please refer to the Wiki Documentation for the complete Global Settings Wizard reference. All versions of the SimpleIndex software include OCR with the Standard/Tesseract OCR engine. The SimpleIndex download only includes a limited set of languages with the installation. If the language you would like to OCR with SimpleIndex isn’t one of the languages included then you can download
Languages Supported in SimpleSoftware OCR Engines
Monday, 02 December 2019
Please refer to the Wiki Documentation for the complete Languages reference. SimpleSoftware OCR engines are using two different systems for language support. In the end languages supported by your OCR is based on your version of SimpleIndex installed, any addons (SimpleIndex Server, SimpleCoversheet, and so on) do not add any additional language support. All SimpleSoftware products have Tesseract 3.02
Change the OCR Font or Type
Monday, 29 July 2019
Please refer to the Wiki Documentation for the complete OCR Options reference. This is used to changed the default OCR recognition font or type from the default, which is “To Be Detected”. This can be used to look for a specific type of OCR font and is especially useful for recognizing things like Dotmatrix, OCR A and OCR B.
I’m using full page OCR. The information is all appearing in the txt file but it is losing format about half way through. Data to the right is ending up at the end of the txt doc. Can this be fixed?
Wednesday, 28 February 2018
Please refer to the Wiki Documentation for the complete Full-Page OCR reference. SimpleIndex version 7 solves this problem with the incorporation of the FineReader OCR engine. Full text in PDFs will now flow with the formatting of the PDF. Legacy Versions: SimpleIndex can also be used with other OCR applications and servers to improve accuracy, formatting and
- Published in OCR
- 1
- 2